 CloudConsole
Amazon Athena pricing explained
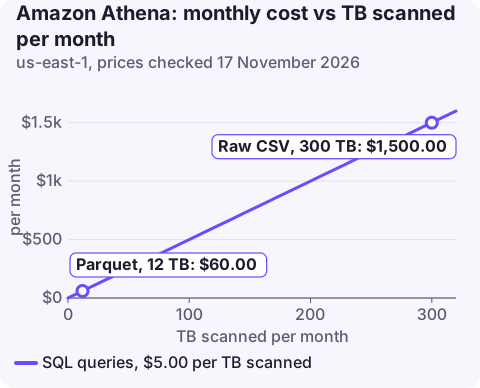
Athena SQL queries cost $5.00 per TB of data scanned in us-east-1 at the time of writing, rounded up to the nearest megabyte with a 10 MB minimum per query. Athena for Apache Spark bills $0.35 per DPU-hour, and provisioned capacity bills $0.30 per DPU-hour for dedicated SQL capacity. S3 storage and requests are billed separately by S3.
Pricing dimensions
| Dimension | Unit | us-east-1 price |
|---|---|---|
| SQL queries | TB scanned | $5.00 |
| Apache Spark | DPU-hour | $0.35 |
| Provisioned capacity | DPU-hour | $0.30 |
From the AWS Price List API at the time of writing. Failed queries are not charged; cancelled queries are charged for the data scanned before cancellation. DDL statements such as CREATE TABLE and partition management are free.
Worked examples
1. Dashboards on raw CSV. 200 queries a day, each scanning 50 GB (0.05 TB): 200 × 30 × 0.05 = 300 TB a month × $5.00 = $1,500.00.
2. The same dashboards on partitioned Parquet. With columnar files and partition filters each query reads 2 GB: 200 × 30 × 0.002 = 12 TB × $5.00 = $60.00. File format and partitioning are the biggest Athena cost levers by far.
3. A Spark notebook. 20 DPUs for 2 hours a day on 22 days: 20 × 2 × 22 = 880 DPU-hours × $0.35 = $308.00.
A common case: querying CloudTrail logs
A year of CloudTrail logs in S3 is often around 0.5 TB of compressed JSON. An Athena table over the whole prefix without partitions scans all of it for every query: 0.5 × $5.00 = $2.50 a query, which adds up quickly during an investigation. Defining the table with partition projection on Region and date and filtering on a single day reads about a 365th of the data, less than a cent per query. Redshift Spectrum bills the same $5.00 per TB scanned, so the same layout advice applies there; see Redshift pricing.
Making queries scan less
- Convert to Parquet or ORC with compression; Athena reads only the columns you select.
- Partition by date (or use partition projection) and always filter on the partition column.
- Avoid
SELECT *on wide tables. - Use workgroups with a per-query data-scanned limit to stop accidental full scans.
- Reuse query results where the workgroup allows it, so repeated dashboard queries are not re-scanned.
Charges outside Athena
- S3 GET and LIST requests from every query, billed by S3; many small files multiply them.
- Query results written to the results bucket, stored until a lifecycle rule removes them.
- Glue Data Catalog requests and storage beyond the free tier; see the Glue pricing page.
- Federated queries run Lambda connectors, billed as Lambda.
- KMS requests for encrypted data and results.
Seeing Athena cost
Cost Explorer shows Athena with usage type USE1-DataScannedInTB. Per-query bytes scanned are in each query's statistics and in workgroup CloudWatch metrics (ProcessedBytes), which show which workgroup or team runs the expensive queries.
Questions
How much does an Athena query cost?
$5.00 per TB scanned in us-east-1 at the time of writing, with a 10 MB minimum per query. A query that scans 10 GB costs about 5 cents.
Does Athena charge for failed queries?
No. Failed queries are not charged; cancelled queries are charged for the data scanned up to the point of cancellation.
How do I reduce Athena cost per query?
Store data as compressed Parquet or ORC, partition it, select only the columns you need, and set data-scanned limits on workgroups.
One unpartitioned query in a scheduled dashboard can run up a large bill quietly. CloudConsole is being built to show costs on a phone, so it is spotted sooner.
About the app → · Download on the App Store